Overview
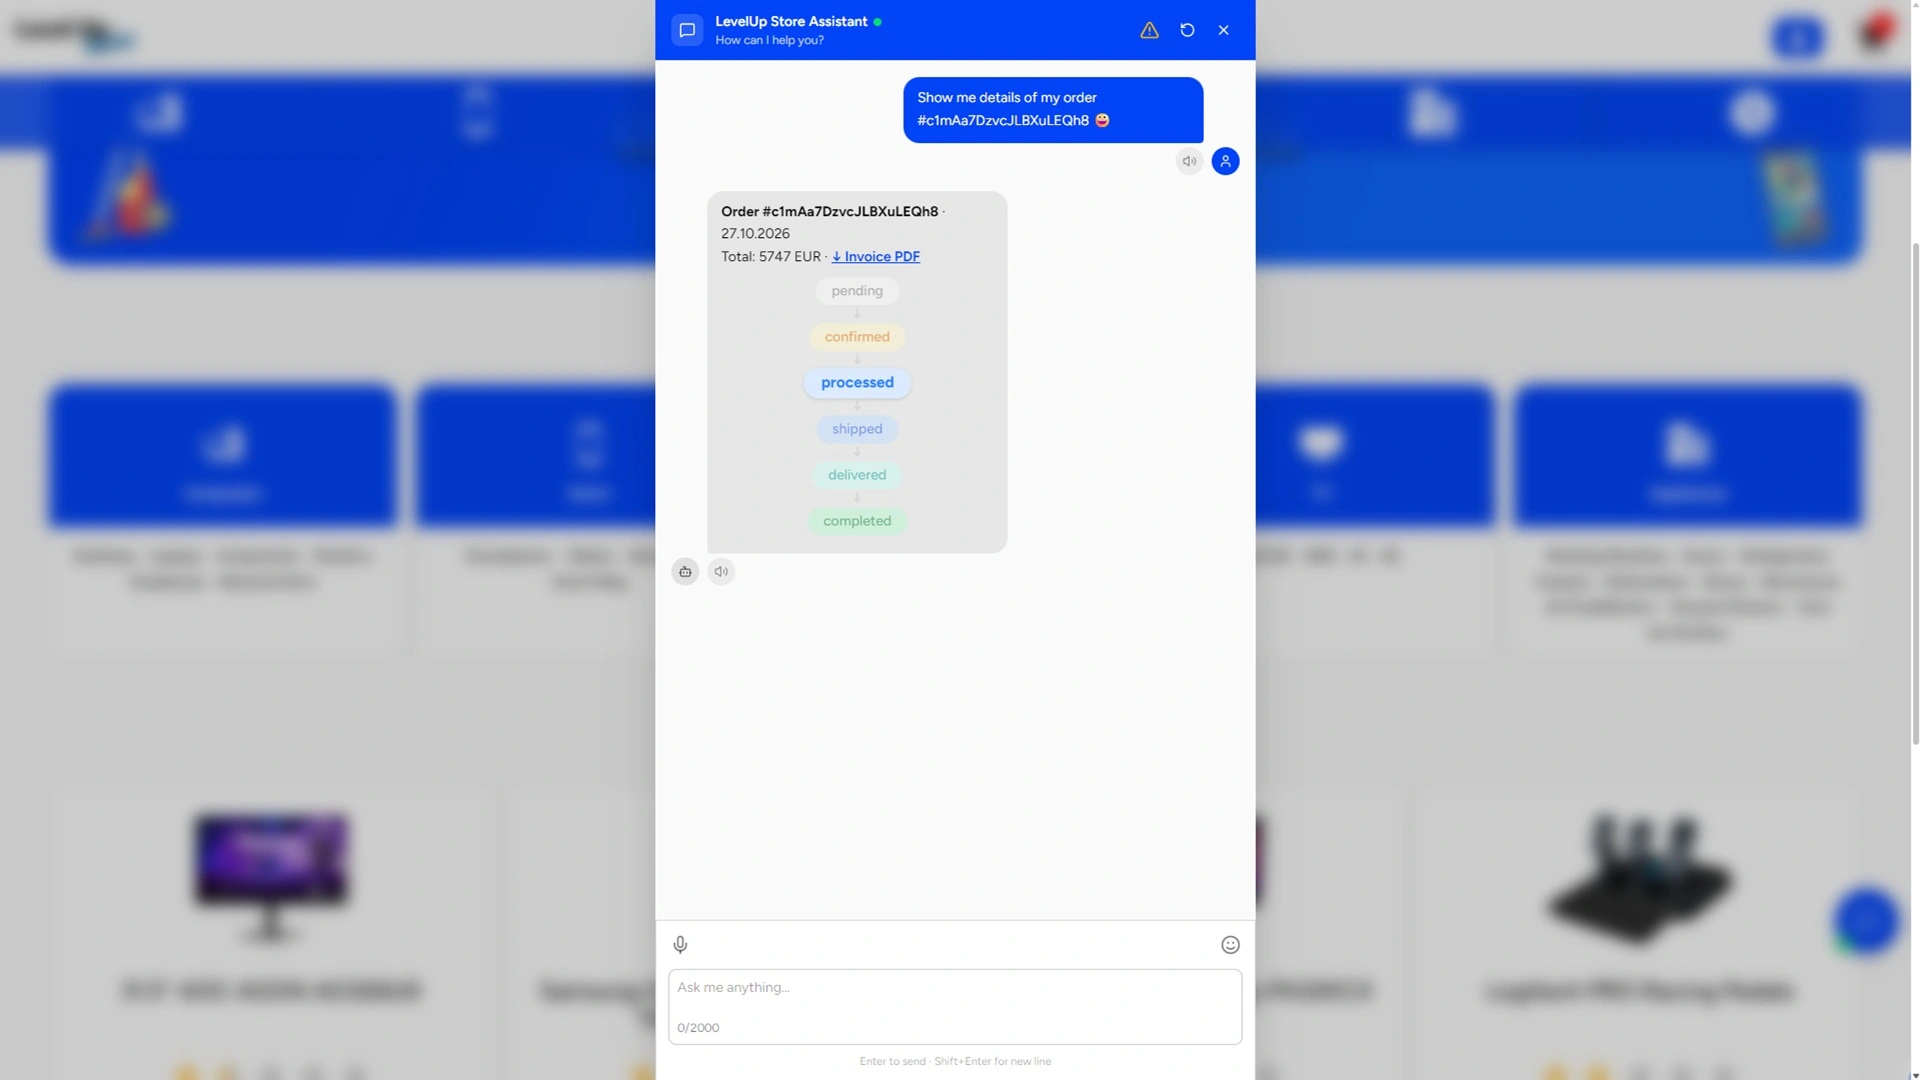
A standalone AI assistant service living inside the LevelUp Store monorepo. Built with FastAPI, it gives users a conversational interface to ask questions about products, categories, availability, reviews, and their own orders - answering from actual store data, not from generic LLM knowledge. Responses are shaped by structured prompt templates. No data leaves the server: the LLM runs locally via Ollama.
Architecture
Chat requests arrive via a RabbitMQ queue (the ai_requests queue, fully decoupled from the e-commerce app). A FastAPI worker processes each request, runs the RAG retrieval against ChromaDB, and passes the context to Ollama. The response is streamed token-by-token back to the browser via Redis pub/sub + SSE, so the user sees output as it is generated. Conversation history is stored in Redis with a 24-hour TTL and tied to a conversation_id, enabling multi-turn dialogue.
Key Features
- RAG pipeline - product catalog and reviews ingested into ChromaDB; relevant context retrieved per query and injected into the prompt via structured prompt templates. Re-ingest with
make ingestafter catalog changes. - User context - for authenticated users, order history is fetched and included in the prompt so the assistant can answer questions about their own purchases
- Local LLM inference runs on-premise via Ollama; no API keys, no external calls, data stays private
- Token streaming - responses appear word by word via Redis pub/sub + server-sent events, no waiting for the full answer
- Async queue -
ai_requestsRabbitMQ queue absorbs AI load, main store HTTP performance is unaffected - Conversation history - stored in Redis (24h TTL); pass
conversation_idfrom the previous response to continue the conversation - Rate limiting - request limit per 5 hours per IP via SlowAPI, with a human-readable retry message
- Health check -
GET /healthmonitors all dependencies: Ollama, Redis, ChromaDB, PostgreSQL - API docs - Swagger UI at
/docs, OpenAPI spec at/openapi.json - React frontend - TypeScript + Tailwind CSS chat interface with token-by-token SSE rendering, microphone input (speech-to-text), stop generation, auto-restore of conversation on page reload, emoji support, and clear chat
- Message caching - conversation messages cached in Redis for guest users; authenticated users have their history tied to their account